import matplotlib.pyplot as plt
import numpy as npReview of Modules 1 to 3
Module 4: IDEs & Tools
Introduction
Use these exercises to review Modules 1 to 3 and to see everything working together. I recommend deactivating Gemini first, along with any other AI helper, and attempting the exercises on your own.
All the exercises are optional. Try each one before opening its collapsed solution, and then compare your work with the worked solution. For programming exercises, test your solution with additional inputs.
Do the exercises in VS Code, as a notebook or as a script, to practise the tools of this module.
Strings and Dictionaries
NoteRemove Duplicates
Write a Python function to remove repeated consecutive characters and replace them with single letters, and return the updated string.
Sample input 1: remove_duplicates("Red Green White")
Expected result 1: "Red Gren White"
Sample input 2: remove_duplicates("aabbbcdeffff")
Expected result 2: "abcdef"
TipSolution
# Solution 1

def remove_duplicates(s):
  """
  Removes repeated consecutive characters in a string
  """
  result = ""
  for char in s:
    if not result or char != result[-1]:
      result += char
  return result

# Test the function with the provided examples
test1 = "Red Green White"
result1 = remove_duplicates(test1)
print(result1)

test2 = "aabbbcdeffff"
result2 = remove_duplicates(test2)
print(result2)
Red Gren White
abcdef# Solution 2
def remove_duplicates(s):
"""
Removes repeated consecutive characters in a string
"""
empty_ls = []
for i in range(0, len(s)-1):
if s[i] != s[i+1]:
empty_ls.append(s[i])
return "".join(empty_ls) + s[-1]
# Test the function with the provided examples
test1 = "Red Green White"
result1 = remove_duplicates(test1)
print(result1)
test2 = "aabbbcdeffff"
result2 = remove_duplicates(test2)
print(result2)Red Gren White
abcdef
NoteInvert Dictionary
Write a Python program to invert a given dictionary with non-unique hashable values.
Sample input: {"fruit": ["apple", "pear"], "veggie": ["pepper"]}
Expected result: {"apple": "fruit", "pear": "fruit", "pepper": "veggie"}
Try this input too:
grades = {
    9: ["Amanda", "Bert"],
    8: ["Charlie", "Denise"],
    7: ["Ernesto", "Fiona", "Gonzalo"],
    6: ["Hilda", "Ignacio", "Jerry"]
}
TipSolution
def invert_dict(dict_in: dict) -> dict:
  dict_out = {}

  for key, ls in dict_in.items():
    for value in ls:
      dict_out[value] = key

  return dict_out

students = invert_dict(grades)

print(students)
{'Amanda': 9, 'Bert': 9, 'Charlie': 8, 'Denise': 8, 'Ernesto': 7, 'Fiona': 7, 'Gonzalo': 7, 'Hilda': 6, 'Ignacio': 6, 'Jerry': 6}Random Numbers
NoteGuessing Game
Generate a random number between 1 and 9 (including 1 and 9). Ask the user to guess the number, then tell them whether they guessed too low, too high, or exactly right.
- Keep the game going until the user types “exit”.
- Keep track of how many guesses the user has taken, and when the game ends, print this out.
TipSolution
import numpy as np

def guessing_game():
  # Generate a random number between 1 and 9: the upper limit is excluded
  number = np.random.randint(1, 10)
  guesses = 0

  while True:
    guess = input("Guess a number between 1 and 9, or type 'exit' to end the game: ")

    if guess.lower() == 'exit':
      break

    guess = int(guess)
    guesses += 1

    if guess < number:
      print("Too low!")
    elif guess > number:
      print("Too high!")
    else:
      print("Exactly right!")
      break

print(f"Game over. You took {guesses} guesses.")guessing_game()np.random.randint(1, 10) returns values from 1 to 9: the upper limit is excluded. With randint(1, 9) the number 9 would never appear.
NoteCard Dealer
Create a Python function to simulate dealing cards from a deck. The function should perform the following tasks:
- Generate a full deck of poker cards. Represent each card as a tuple, where the first element is the number or figure (e.g., “King”, “3”), and the second element is the suit (e.g., “Hearts”, “Spades”). The deck should include all standard cards (13 cards per suit) and two jokers, resulting in a total of 54 cards. For example, the 10 of Hearts is represented as
(10, "Hearts"). - Shuffle the deck. The function should randomize the order of the cards in the deck.
- Deal cards to players. The function should accept two parameters: the list of player names and the number of cards to deal to each player. Distribute the specified number of cards from the shuffled deck to each player.
The output should be a dictionary of lists, like {"Daniel": [("3", "Diamonds"), ("Jack", "Clovers")]}.
TipSolution
# Solution 1

import numpy as np

def create_deck():
  """
  Creates a full deck of poker cards including two jokers.
  Each card is represented as a tuple (value, suit).
  """
  suits = ["Hearts", "Diamonds", "Clubs", "Spades"]
  values = ["2", "3", "4", "5", "6", "7", "8", "9", "10", "Jack", "Queen", "King", "Ace"]
  deck = [(value, suit) for suit in suits for value in values]

  # Add two Jokers
  deck.extend([("Joker", "Red"), ("Joker", "Black")])

  return deck

def shuffle_deck(deck):
    """
    Shuffles the given deck of cards.
    """
    np.random.shuffle(deck)
    return deck

def deal_cards(deck, players, cards_per_player):
  """
  Deals a specified number of cards to each player.
  """
  if len(players) * cards_per_player > len(deck):
    raise ValueError("Not enough cards in the deck to deal to all players.")

  hands = {player: [] for player in players}
  for _ in range(cards_per_player):
    for player in players:
      hands[player].append(deck.pop())

  return hands

# Example usage
deck = create_deck()
shuffled_deck = shuffle_deck(deck)
player_hands = deal_cards(shuffled_deck, ["Daniel", "Emma", "Lucas", "Sophia"], 2)  # 4 players, 2 cards each

print(player_hands)
{'Daniel': [('Queen', 'Hearts'), ('8', 'Clubs')], 'Emma': [('4', 'Diamonds'), ('7', 'Spades')], 'Lucas': [('7', 'Clubs'), ('8', 'Spades')], 'Sophia': [('King', 'Diamonds'), ('10', 'Hearts')]}# Solution 2 (the first two steps only: a deck without jokers and a random hand)
import numpy as np
def create_deck() -> list:
ls_suits = ["hearts", "diamonds", "clubs", "spades"]
ls_values = np.arange(2, 11)
ls_values = np.append(ls_values, ["J", "Q", "K", "A"])
ls_deck = []
for suit in ls_suits:
for value in ls_values:
ls_deck.append((value, suit))
return ls_deck
def deal_random_hand(ls_deck: list, num_cards: int = 5) -> list:
"""
Deals a random hand of cards from a deck.
The function removes the dealt cards from the deck.
"""
ls_hand = []
while len(ls_hand) < num_cards:
idx = np.random.randint(0, len(ls_deck))
card = ls_deck.pop(idx)
ls_hand.append(card)
return ls_handNumPy Functions
NoteLog-Sum-Exp Function
Create a NumPy function named log_sum_exp which computes the natural logarithm (base e) of the sum of the exponentials of the input elements. This is a common operation in many statistical computations.
Sample input: log_sum_exp(np.array([1, 2, 3]))
Expected result: 3.40760596444438
TipSolution
import numpy as np

def log_sum_exp(arr):
  """
  Computes the logarithm of the sum of exponentiations of the input elements:
  Natural logarithm of the sum of exponentials (base e)
  """
  exp_sum = np.sum(np.exp(arr))
  log_sum_exp_base_e = np.log(exp_sum)

  return log_sum_exp_base_e

# Example array
array = np.array([1, 2, 3])

# Compute the log-sum-exp for the example array
log_sum_exp_result = log_sum_exp(array)
print(log_sum_exp_result)
3.40760596444438
NoteNumPy Difference
Write a NumPy program to calculate the difference between neighboring elements, element-wise, and prepend [0, 0] and append [200] to a given array.
Sample input: [1, 3, 5, 7, 0]
Expected result: [ 0, 0, 2, 2, 2, -7, 200]
TipSolution
import numpy as np

def difference_and_append_prepend(arr):
  """
  Calculate the difference between neighboring elements, element-wise,
  and prepend [0, 0] and append [200] to the given array.
  """
  # Calculate differences
  diff = np.diff(arr, n=1)

  # Prepend [0, 0] and append [200]
  result = np.concatenate(([0, 0], diff, [200]))

  return result

# Example array
example_array = np.array([1, 3, 5, 7, 0])

# Apply the function
result = difference_and_append_prepend(example_array)
print(result)
[ 0 0 2 2 2 -7 200]Regression with the Normal Equation
NoteLinear Regression
You have a set of points in a 2D plane, defined by the array pts.
The code below defines the points and plots them.
pts = np.array([[1, 2, 3, 4, 5, 6], [0.6, 1.4, 3.2, 3.4, 5.3, 6.6]])

# The following code uses matplotlib
# You will learn about it in the 2nd semester
plt.plot(pts[0], pts[1], 'ro', label="Data")
plt.legend()
plt.xlabel("X-axis")
plt.ylabel("Y-axis")
plt.show()
plt.close()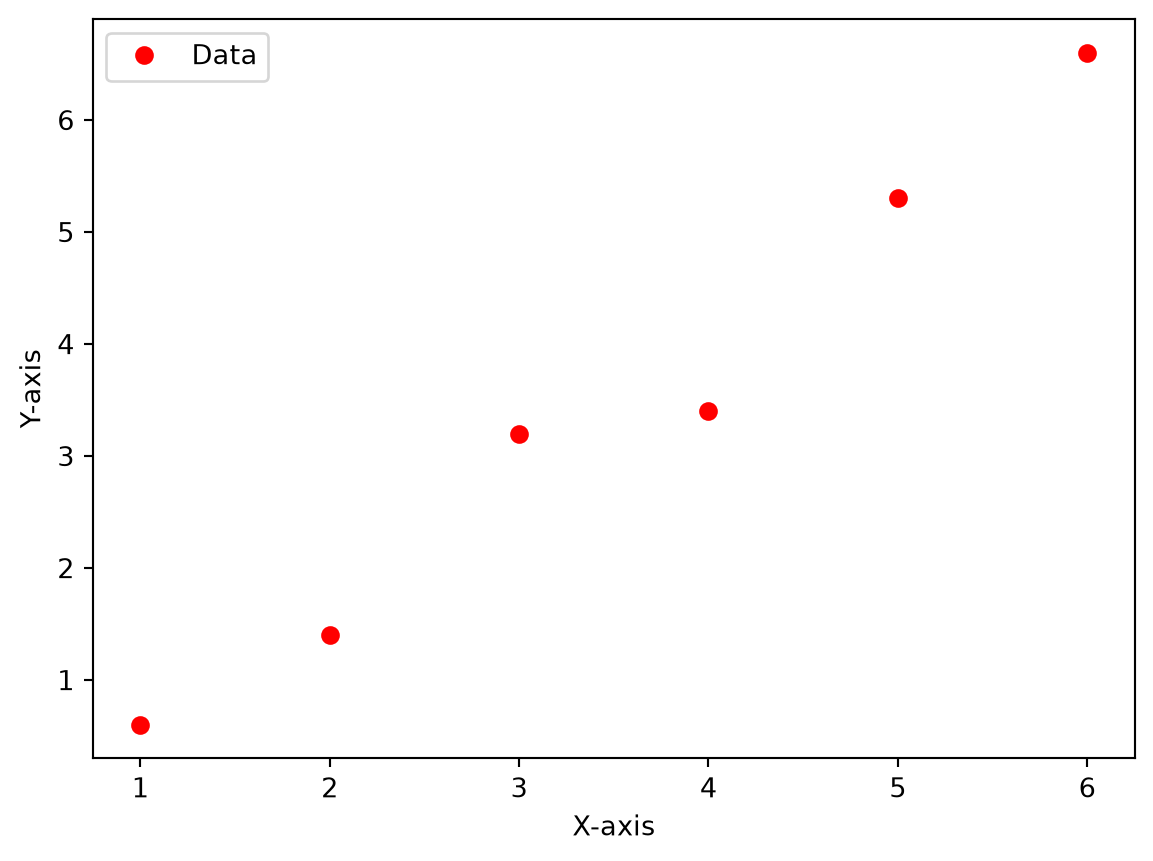
Assuming a set of \(N\) points \((x_i, y_i)\), we can try to fit a straight line so that:
\[y_i = b_0 + b_1 \cdot x_i,\qquad \forall i \in [1, N]\]
In matrix notation, the equation above is:
\[\mathbf{Y} = X \cdot \mathbf{b}\]
where:
\[\mathbf{Y} = (y_1, ..., y_N)\]
\[X = \begin{pmatrix} 1 & x_1 \\ \vdots & \vdots \\ 1 & x_N \end{pmatrix} \]
\[\mathbf{b} = (b_0, b_1)\]
We will use the Ordinary Least Squares method to fit the points in pts. Compute \(\mathbf{b}\) using the Normal Equation:
\[\mathbf{b} = \left(X^T \cdot X\right)^{-1} \cdot X^T \cdot Y\]
TipSolution
# Extract x and y from the set of points
x, y = pts

# Generate the matrix X
ones = np.ones(len(x))
X = np.vstack([ones, x]).T

# Compute the vector b
# @ = np.matmul
b = np.linalg.inv(X.T @ X) @ X.T @ y

# Now we can use the vector b to estimate any value of y
# Let's visualize the line defined by b
x_line = np.linspace(x[0], x[-1], 100)
y_line = b[0] + b[1] * x_line

# The following code uses matplotlib
# You will learn about it in the 2nd semester
plt.plot(x, y, 'ro', label="Data")
plt.plot(x_line, y_line, 'b-', label="Line")
plt.legend()
plt.xlabel("X-axis")
plt.ylabel("Y-axis")
plt.show()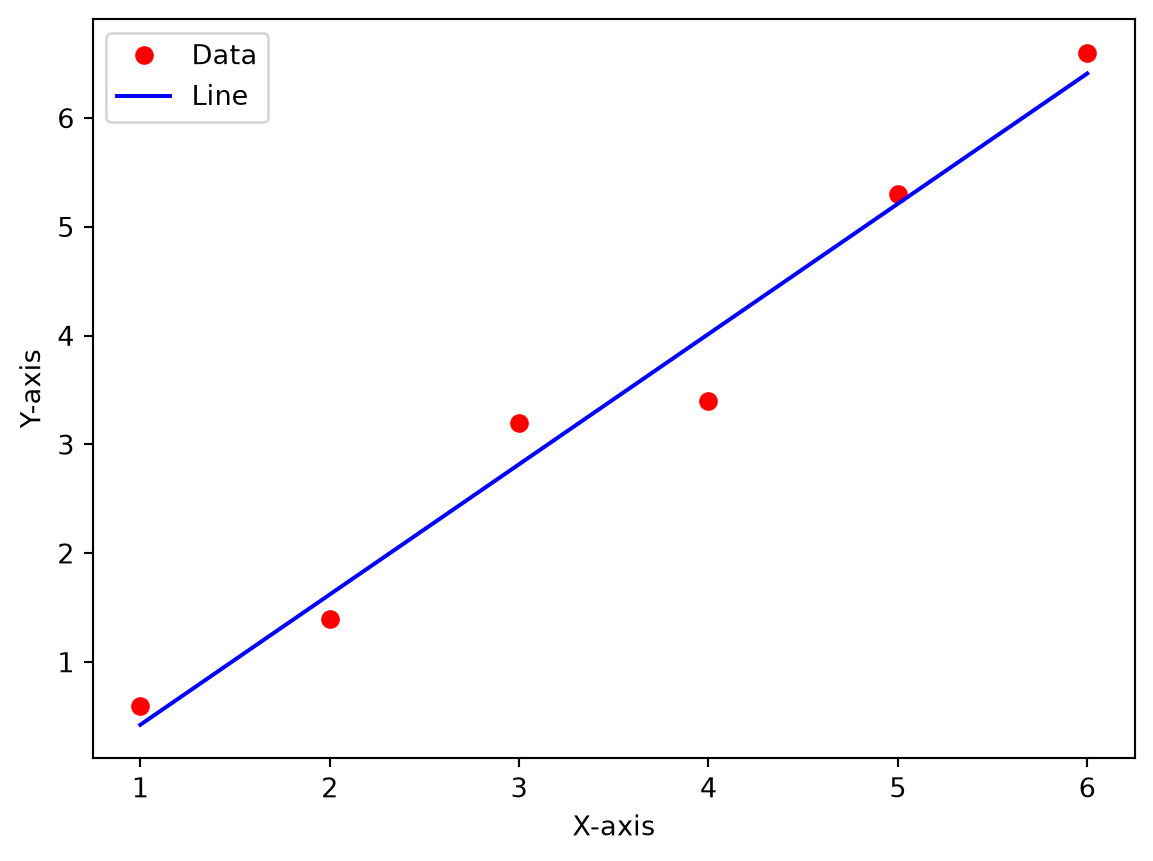
NoteQuadratic Regression
What if you wanted to fit a quadratic expression? You would need to change the arrays \(X\) and \(\mathbf{b}\) inside the Normal Equation of the previous exercise:
\[\mathbf{Y} = (y_1, ..., y_N)\]
\[X = \begin{pmatrix} 1 & x_1 & x_1^2\\ \vdots & \vdots & \vdots \\ 1 & x_N & x_N^2 \end{pmatrix} \]
\[\mathbf{b} = (b_0, b_1, b_2)\]
- Generate any number of \((x, y)\) points following the expression \(y = 2x - x^2\). Then add some noise to the values of \(y\). You can, for instance, add a random value from a normal distribution: \(\hat{y} = y + \text{N}(0, 1)\).
- Do a regression on \((x, \hat{y})\) with the Normal Equation.
TipSolution
# Part 1

# Generate 10 values of (x, y)
x = np.linspace(-2, 2, 10)
y = 2 * x - np.power(x, 2)

# Add noise to y
y_hat = y + np.random.normal(0, 1, len(x))

# Plot both original and noisy points
# The following code uses matplotlib
# You will learn about it in the 2nd semester
plt.plot(x, y, 'bo', label="Original")
plt.plot(x, y_hat, 'ro', label="Noisy")
plt.legend()
plt.xlabel("X-axis")
plt.ylabel("Y-axis")
plt.show()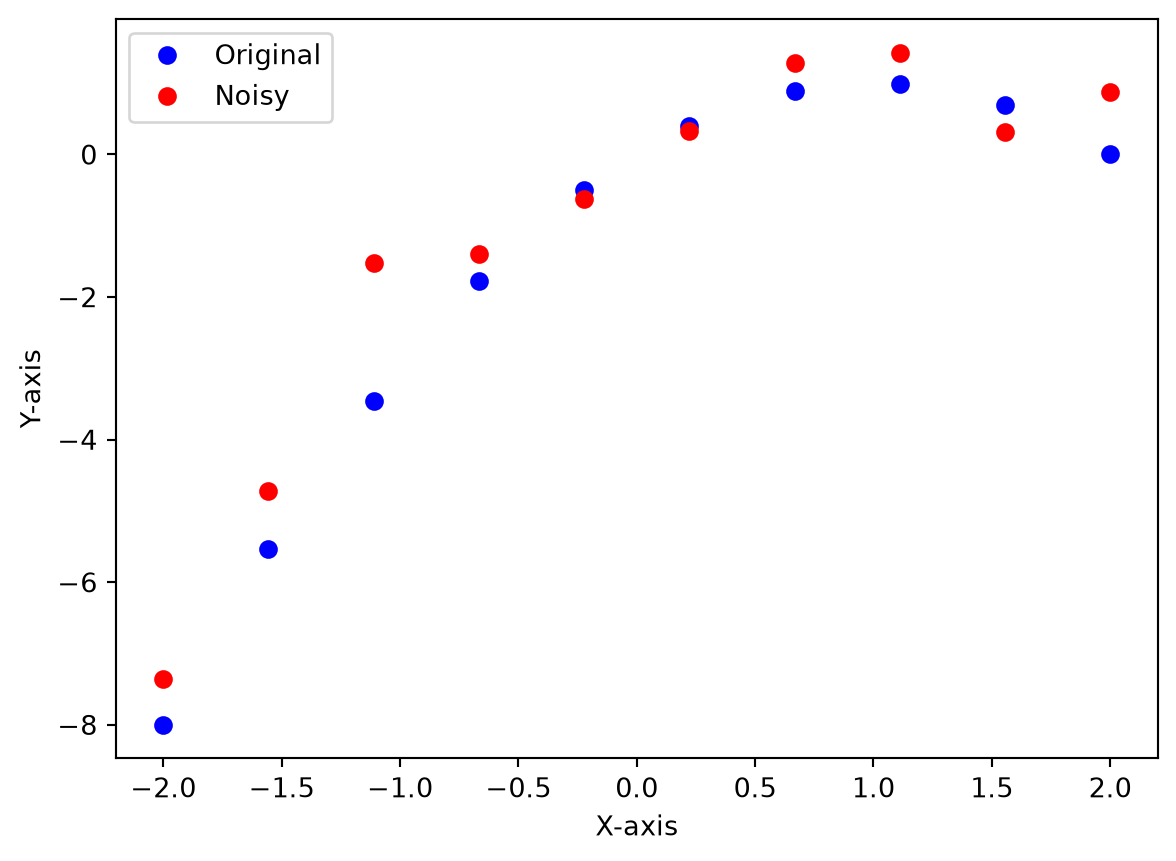
# Part 2

# Generate the matrix X
ones = np.ones(len(x))
x2 = np.power(x, 2)
X = np.vstack([ones, x, x2]).T

# Compute the vector b
b = np.linalg.inv(X.T @ X) @ X.T @ y_hat

# Now we can use the vector b to estimate any value of y
# Let's visualize the curve defined by b
x_line = np.linspace(x[0], x[-1], 100)
y_line = b[0] + b[1] * x_line + b[2] * np.power(x_line, 2)

# The following code uses matplotlib
# You will learn about it in the 2nd semester
plt.plot(x, y_hat, 'ro', label="Data (Noisy)")
plt.plot(x_line, y_line, 'b-', label="Curve")
plt.legend()
plt.xlabel("X-axis")
plt.ylabel("Y-axis")
plt.show()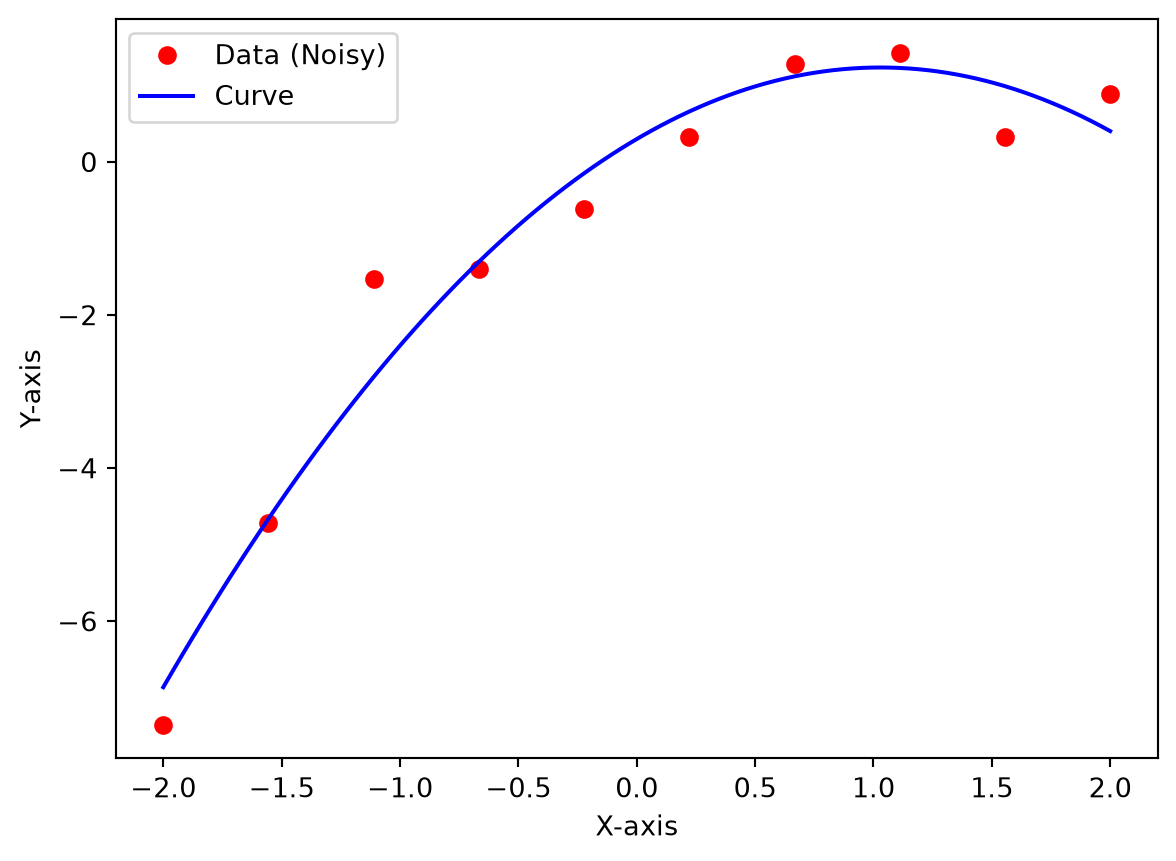
Debugging Questions
NoteDebugging: Duplicates in a List
The following code is intended to remove duplicates from a list while preserving the original order of elements. However, it raises the error AttributeError: 'dict' object has no attribute 'add'. Identify and fix the error(s).
def remove_duplicates(seq: list) -> list:
  seen = {}
  result = []
  for item in seq:
    if item in seen:
      continue
    else:
      seen.add(item)  # Error
    result.append(item)
    return result

original_list = [5, 4, 3, 4, 5, 2, 1]
new_list = remove_duplicates(original_list)
print("New List:", new_list)  # Expected: [5, 4, 3, 2, 1]
TipSolution
def remove_duplicates(seq: list) -> list:
  seen = set()
  result = []
  for item in seq:
    if item in seen:
      continue
    else:
      seen.add(item)
    result.append(item)
  return result

original_list = [5, 4, 3, 4, 5, 2, 1]
new_list = remove_duplicates(original_list)
print("New List:", new_list)  # Expected: [5, 4, 3, 2, 1]
New List: [5, 4, 3, 2, 1]Two errors: seen must be a set ({} creates an empty dictionary, which has no add), and return result must be outside the loop.
NoteDebugging: Swapping a Tuple
This code attempts to swap the values of two variables stored in a tuple without using a temporary variable. However, it results in the error TypeError: 'tuple' object does not support item assignment. Identify and fix the issue(s).
def swap_values(tup: tuple) -> tuple:
  tup[0], tup[1] = tup[1], tup[0]  # Error

my_tuple = (10, 20)
swapped_tuple = swap_values(my_tuple)
print("Swapped Tuple:", swapped_tuple)  # Expected: (20, 10)
TipSolution
def swap_values(tup: tuple) -> tuple:
  ls = list(tup)
  ls[0], ls[1] = ls[1], ls[0]
  return tuple(ls)

my_tuple = (10, 20)
swapped_tuple = swap_values(my_tuple)
print("Swapped Tuple:", swapped_tuple)  # Expected: (20, 10)
Swapped Tuple: (20, 10)Tuples are immutable: we convert to a list, swap, and convert back. The original function also forgot to return anything.
NoteDebugging: Removing a Value (IndexError)
This code tries to modify a list while iterating over it to remove all occurrences of a specific value. However, it raises the error IndexError: list index out of range. Identify and fix the error(s).
def remove_value(lst: list, val: int) -> list:
  for i in range(len(lst)):
    if lst[i] == val:  # Error
      lst.pop(i)
  return lst

numbers = [1, 2, 3, 2, 4, 2, 5]
updated_numbers = remove_value(numbers, 2)
print("Updated Numbers:", updated_numbers)  # Expected: [1, 3, 4, 5]
TipSolution
def remove_value(lst: list, val: int) -> list:
  result = []
  for i in range(len(lst)):
    if lst[i] != val:
      result.append(lst[i])
  return result

numbers = [1, 2, 3, 2, 4, 2, 5]
updated_numbers = remove_value(numbers, 2)
print("Updated Numbers:", updated_numbers)  # Expected: [1, 3, 4, 5]
Updated Numbers: [1, 3, 4, 5]
NoteDebugging: Removing a Value (Missed Items)
This code tries to modify a list while iterating over it to remove all occurrences of a specific value. However, it doesn’t remove all instances as intended. Identify and fix the error(s).
def remove_value(lst: list, val: int) -> list:
  for item in lst:
    if item == val:
      lst.remove(item)
  return lst

numbers = [1, 2, 3, 2, 4, 2, 2, 5]
updated_numbers = remove_value(numbers, 2)
print("Updated Numbers:", updated_numbers)
# Expected: [1, 3, 4, 5]
# Output: [1, 3, 4, 2, 5]
TipSolution
Never modify the list you are looping through: removing an item shifts the following ones, and the loop skips them. Build a new list instead, as in the previous exercise.
NoteDebugging: Flatten a List
This code is supposed to flatten a list of lists into a single list. However, it raises the error TypeError: 'int' object is not iterable. Find and fix the error(s).
def flatten(lst: list[list]) -> list:
  flat_list = []
  for sublist in lst:
    flat_list.extend(sublist)  # Error
  return flat_list

nested_list = [1, [2, 3], [4, [5, 6]], 7]
flattened = flatten(nested_list)
print("Flattened List:", flattened)
# Expected: [1, 2, 3, 4, 5, 6, 7]
TipSolution
def flatten(lst: list) -> list:
  flat_list = []
  for item in lst:
    if isinstance(item, list):
      flat_list.extend(flatten(item))  # a sublist: flatten it first
    else:
      flat_list.append(item)           # a single value: add it
  return flat_list

nested_list = [1, [2, 3], [4, [5, 6]], 7]
flattened = flatten(nested_list)
print("Flattened List:", flattened)
# Expected: [1, 2, 3, 4, 5, 6, 7]
Flattened List: [1, 2, 3, 4, 5, 6, 7]extend needs an iterable, but 1 and 7 are integers, which is the TypeError. Besides, the list has several levels ([4, [5, 6]]), so a single extend would not be enough. The function checks each item: a list is flattened by calling the function again (recursion), and any other value is appended. The type hint list[list] was also wrong, because the items are not all lists.
NoteDebugging: Character Frequency
The code aims to count the frequency of each character in a string using a dictionary. However, it raises the error KeyError: 'h'. Find and correct the error(s).
def char_frequency(s: str) -> int:
  freq = dict()
  for char in s:
    if char.isalpha():
      freq[char] += 1  # Error
  return freq

text = "hello world"
frequency = char_frequency(text)
print("Character Frequency:", frequency)
# Expected: {'h': 1, 'e': 1, 'l': 3, 'o': 2, 'w': 1, 'r': 1, 'd': 1}
TipSolution
def char_frequency(s: str) -> dict:
  freq = dict()
  for char in s:
    if char.isalpha():
      freq[char] = freq.get(char, 0) + 1
  return freq

text = "hello world"
frequency = char_frequency(text)
print("Character Frequency:", frequency)
# Expected: {'h': 1, 'e': 1, 'l': 3, 'o': 2, 'w': 1, 'r': 1, 'd': 1}
Character Frequency: {'h': 1, 'e': 1, 'l': 3, 'o': 2, 'w': 1, 'r': 1, 'd': 1}freq[char] += 1 reads the current value first, but the first time a character appears it is not in the dictionary yet: KeyError. With freq.get(char, 0) we use 0 when the key does not exist. The return type hint was also wrong: the function returns a dict, not an int.
NoteDebugging: Merging Dictionaries
The following code is meant to merge two dictionaries, summing the values of common keys. However, it doesn’t produce the expected result. Identify and fix the error(s).
def merge_dicts(d1: dict, d2: dict) -> dict:
  merged = d1.copy()
  for key in d2.keys():
    if not (key in d1.keys()):
      continue
    merged[key] = d1.get(key, 0) + d2[key]
  return merged

dict_a = {'apple': 10, 'banana': 5}
dict_b = {'banana': 15, 'cherry': 20}
merged_dict = merge_dicts(dict_a, dict_b)
print("Merged Dictionary:", merged_dict)
# Expected: {'apple': 10, 'banana': 20, 'cherry': 20}
# Output: {'apple': 10, 'banana': 20}
TipSolution
def merge_dicts(d1: dict, d2: dict) -> dict:
  merged = d1.copy()
  for key in d2:
    merged[key] = merged.get(key, 0) + d2[key]
  return merged

dict_a = {'apple': 10, 'banana': 5}
dict_b = {'banana': 15, 'cherry': 20}
merged_dict = merge_dicts(dict_a, dict_b)
print("Merged Dictionary:", merged_dict)
# Expected: {'apple': 10, 'banana': 20, 'cherry': 20}
Merged Dictionary: {'apple': 10, 'banana': 20, 'cherry': 20}The continue skipped every key of d2 that is not in d1, so 'cherry' was lost. We do not need that check: merged.get(key, 0) returns the current value, or 0 for a new key, and then we add the value of d2.
NoteDebugging: Unique Lists
This code attempts to create a set of tuples from a list of lists, intending to remove duplicate lists. However, it raises the error TypeError: unhashable type: 'list'. Identify and fix the issue(s).
list_of_lists = [[1, 2], [3, 4], [1, 2]]
unique_sets = set(list_of_lists)  # Error
print("Unique Sets:", unique_sets)  # Expected: {(1, 2), (3, 4)}
TipSolution
list_of_lists = [[1, 2], [3, 4], [1, 2]]
unique_sets = set(tuple(item) for item in list_of_lists)
print("Unique Sets:", unique_sets)  # Expected: {(1, 2), (3, 4)}
Unique Sets: {(1, 2), (3, 4)}Set elements must be hashable, and lists are not, because they are mutable: TypeError: unhashable type: 'list'. Tuples are immutable and hashable, so we convert each inner list with tuple(...) before building the set.
Debugging Questions (NumPy)
NoteDebugging: Reshape
The code aims to reshape a flat array into a 3D array. However, it results in an error. Identify and fix the error(s).
arr = np.arange(27)
arr_3d = arr.reshape((3, 3))  # Error
print("3D Array:\n", arr_3d)
TipSolution
arr = np.arange(27)
arr_3d = arr.reshape((3, 3, 3))
print("3D Array:\n", arr_3d)
3D Array:
[[[ 0 1 2]
[ 3 4 5]
[ 6 7 8]]
[[ 9 10 11]
[12 13 14]
[15 16 17]]
[[18 19 20]
[21 22 23]
[24 25 26]]]The array has 27 elements, and a shape of (3, 3) only holds 9 (ValueError: cannot reshape array of size 27 into shape (3,3)). Besides, (3, 3) is a 2D shape. A 3D array needs three dimensions whose product is 27, for example (3, 3, 3). You can also leave one dimension for NumPy to infer: arr.reshape((3, 3, -1)).
NoteDebugging: Cumulative Product
The code is supposed to compute the cumulative product of an array. However, it gives incorrect output. Identify and fix the error(s).
arr = np.array([[1, 2, 3, 4]])

cum_prod = np.cumsum(arr, axis=0)
print("Cumulative product:", cum_prod)
# Expected: [[1, 2, 6, 24]]
# Output: [[1 2 3 4]]
TipSolution
arr = np.array([[1, 2, 3, 4]])

cum_prod = np.cumprod(arr, axis=1)
print("Cumulative product:", cum_prod)
# Expected: [[1, 2, 6, 24]]
Cumulative product: [[ 1 2 6 24]]There are two errors. np.cumsum computes a cumulative sum, and we need np.cumprod. And axis=0 accumulates down the rows, but this array has only one row, so nothing changes. The values we want to accumulate are along the columns, which is axis=1.
NoteDebugging: Selecting with a Condition
This code attempts to select elements from a NumPy array based on a condition. However, it raises the error ValueError: The truth value of an array with more than one element is ambiguous. Use a.any() or a.all(). Identify and fix the error(s).
arr = np.arange(10)

# Select elements greater than 5 and less than 8
selected = arr[arr > 5 and arr < 8.0]  # Error
print("Selected elements:", selected)  # Expected: [6, 7]
TipSolution
arr = np.arange(10)

# Select elements greater than 5 and less than 8
selected = arr[(arr > 5) & (arr < 8.0)]
print("Selected elements:", selected)  # Expected: [6 7]
Selected elements: [6 7]and compares two single truth values, but arr > 5 is an array of booleans, so Python does not know how to decide: ValueError. For arrays we use & (and), | (or) and ~ (not), which work element by element. The parentheses are required, because & binds more tightly than > and <.
NoteDebugging: A Fixed Seed
You wrote the following code to see how fixing a seed ensures the random generators always return the same number. However, every step of the for loop shows a different number. What is happening?
for _ in range(10):
  x = np.random.randint(low=0, high=1000)
  np.random.seed(x)
  print(x)
TipSolution
for _ in range(10):
  np.random.seed(42)   # the same fixed number before each draw
  x = np.random.randint(low=0, high=1000)
  print(x)
102
102
102
102
102
102
102
102
102
102The seed must be a fixed number that we choose. In the original code the seed was x, a number that had just been drawn at random and was different at every step, so each draw started from a different state. (The very first draw happened before any seed was set, so it was random too.) With np.random.seed(42) right before each draw, all ten numbers are the same.
If you set the seed once, before the loop, you get ten different numbers, but the same ten every time you run the program: that is what reproducibility means. In new code you can use a generator, rng = np.random.default_rng(42), and then rng.integers(0, 1000).